“AI-powered building” is on every vendor’s slide right now, and most of it is marketing wrapped around a dashboard. That is a shame, because there is a genuine, useful role for AI in building automation — it is just narrower and less magical than the pitch. Here is an honest separation of what is real from what is hype, from a team that builds the Niagara systems underneath it.
The Hype: An AI That “Runs Your Building”
The overselling usually sounds like autonomy: an AI that takes over control, optimizes everything on its own, and needs no supervision. Be skeptical. Building control is a safety-relevant, physical-consequence domain — equipment can be damaged, occupants made uncomfortable, energy wasted — and handing open-loop control to a system that cannot explain its decisions is not innovation, it is risk. The sequences of operation that run your equipment are deterministic for good reasons. AI does not change that, and the responsible applications keep a human and a hard control layer firmly in the loop.
The Real Value: Insight, Not Autonomy
Where AI and analytics genuinely help is in making sense of data a human cannot watch all of:
- Fault detection. Spotting that a valve is stuck, a sensor has drifted, or a unit is short-cycling — patterns buried in thousands of points that no one is watching in real time.
- Anomaly flagging. Surfacing “this is behaving unlike it normally does” so a person can investigate before it becomes a failure or a complaint.
- Energy insight. Finding where consumption does not match occupancy or conditions, and where the recoverable waste actually is.
- Natural-language access. Letting an operator ask questions of building data in plain language instead of building a report — a genuinely useful interface, and a safe one, because it reads rather than controls.
Notice the pattern: the credible applications inform and recommend; they do not seize control. AI proposes, the deterministic control system and the operator dispose. That boundary is exactly where the value is real and the risk is manageable.
None of It Works Without the Foundation
Here is the part the AI vendors skip: every one of those applications depends entirely on the quality of the data underneath. AI on a building whose points are unmapped, mislabeled, badly scaled, or inconsistently named produces confident nonsense. The unglamorous work — correct integration across BACnet and Modbus, clean point mapping, and consistent semantic tagging — is what makes any of the intelligent layer possible. You cannot analyze data you have not modeled. The building-automation foundation is not the boring prerequisite to the AI; it is the thing that determines whether the AI works at all.
How We Think About It
SoftwarePile builds the Niagara systems and the clean, structured data that any real building intelligence has to stand on. When an AI layer genuinely fits — retrieval-grounded question answering over building data, or analytics that inform operators — our sister practice Software Depo builds AI for exactly these environments, with the same insistence on keeping humans in control and answers grounded in real data. Different specialties, one honest approach: get the foundation right first, add intelligence where it earns its place.
If you are being pitched an “AI building” and want a straight answer about what is worth doing, tell us what you are trying to achieve — we will tell you honestly which parts are real for your building and which are slideware.
What an Analytics Layer Actually Reads
The distance between "the building has data" and "something can analyze it" is mostly a question of how much each source says about itself. A value on its own is a number. What makes it analyzable is knowing what it measures, in what units, on which piece of equipment, and how that equipment relates to everything around it. That description exists somewhere on every project. The only real question is whether it lives in the station, where the people making changes to the building can see it, or gets rebuilt by hand inside the analytics tool, once per site, and maintained there.
Where you read from also carries a cost that has nothing to do with modeling. An analytics layer polling the field network directly becomes another client competing for the same bus, and on BACnet MS/TP over RS-485 the token passing rate, together with Max_Master and Max_Info_Frames, puts a hard ceiling on how much can be requested per second. A second poller there can slow the loops the controllers are actually executing. A station that already holds current values and histories is the cheaper read, and it does not put analytics traffic on wire that control depends on.
Sources differ sharply in how much of the description they carry:
- A Niagara station with a tagged model. Points resolve by path, facets carry units and type, history extensions exist where collection was configured, and tags and relations record which equipment a point belongs to and what that equipment serves. A question resolves to a specific point rather than to a string that resembles one.
- A Niagara station without tagging. The points and histories are there and the names are usually consistent, but consistent is not semantic. Retrieval falls back to matching name fragments, so every question becomes a question about the naming convention, and any equipment commissioned by a different hand is a separate special case.
- Exports and reports. A CSV or a report export is whatever columns the exporter chose, frozen at the moment it ran. Units appear in the header if they appear at all, and timestamps are frequently written in site local time with no UTC offset.
- Direct protocol polling. Modbus TCP on port 502 returns 16-bit register values with no self-description at all: type, scale, sign and meaning live in the vendor's register map document and nowhere on the wire. BACnet/IP on UDP 47808 tells you considerably more, since Object_Name is required and unique within the device, analog objects carry a required Units property of type BACnetEngineeringUnits, and a device may already hold Trend Log or Trend Log Multiple objects readable with ReadRange. What no BACnet read gives you is equipment relations: which air handler that discharge temperature belongs to, and which terminal units it serves. The standard's optional Structured View object can express a hierarchy, but you cannot count on finding one.
History Collection Decides the Answer Before Anyone Analyzes Anything
An interval history samples, and the sample rate is a ceiling on everything downstream of it. A status point collected on a fifteen minute Boolean interval extension cannot show a compressor short cycling on a five minute period; the series looks calm because the collection is aliasing the behavior, not because the equipment is stable. Nothing in the analytics layer recovers information the collection never captured, which makes the interval a design decision about the questions you intend to ask, taken before anyone asks the first one.
Change-of-value collection has the opposite property. Records appear only when the value moves past the configured delta, so a genuinely steady value and a dead sensor produce the same thing, which is nothing. COV series are also irregular, and most analysis wants a regular grid, so a resampling step exists somewhere whether or not anyone chose it. Whether that step holds the last value across a gap, interpolates across it, or marks it missing changes the number the analysis reports.
Capacity and transport set the rest. A Niagara history extension with a record count capacity and a Full Policy of Roll discards its oldest record once full, so retention is a function of collection rate: at one minute a point writes 1,440 records a day, so a 10,000 record capacity holds roughly a week, where the same capacity at fifteen minutes holds roughly three months. Histories collected on a JACE and archived to a Supervisor transfer by record, so a gap that opens on the Supervisor during a link outage generally backfills once the link returns. A gap still sitting there after the link is healthy is a different problem, and worth separating from the first one before anybody starts explaining the data.
Three symptoms that get misread as equipment or sensor problems:
- Two points on the same equipment disagree about when an event happened. Check the clock before the sensors: history records are stamped by the station that collected them, so a JACE whose time has drifted from the Supervisor stamps everything it owns with that offset.
- A value sits perfectly constant for hours. Read the status, not just the value. A driver holding a last known value, a point left out of service, and a manual override all present as clean data to anything reading value alone; Niagara status flags and the BACnet Status_Flags and Reliability properties are where the difference is visible.
- One hour appears twice, or disappears entirely, once or twice a year. That is a timestamp written in local time with no UTC offset meeting a daylight saving transition, and it quietly corrupts any comparison spanning the boundary.
Advisory Is a Wiring Decision, Not a Description
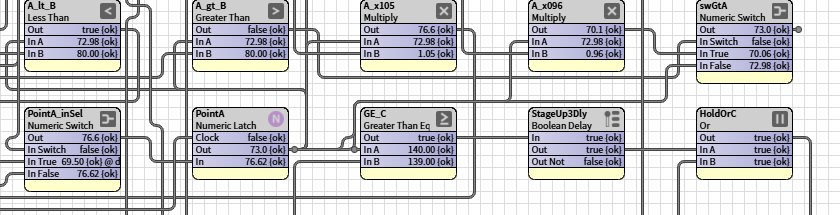
If anything ever writes back, the mechanism decides whether the word advisory means anything. On BACnet, writes to a commandable object arbitrate through a sixteen level priority array in which the lowest numbered active entry wins and Relinquish_Default applies when every level is NULL. The standard assigns 1 and 2 to life safety, 5 to critical equipment control, 6 to minimum on and off timing, and 8 to manual operator, which leaves 9 through 16 available for supervisory and optimization writes. A recommendation written at 14 is therefore a recommendation in the literal sense: an operator at 8, and every interlock below that, take it away without anyone touching the analytics layer.
The failure that follows write-back is the write nobody relinquishes. A supervisory process that commands a value at some priority and then stops, crashes, or loses its network path leaves that entry populated indefinitely, and the local sequence has no way to reclaim a level it does not own, so the equipment stays commanded to a decision made from data that is now days old. There is a useful asymmetry here: a COV subscription is issued with a Lifetime and lapses when it is not renewed, while a property write carries no expiry at all. Anything that writes needs either a heartbeat that relinquishes to NULL on timeout, or logic in the station that clears the level when the supervisory link is absent.
Four decisions have to be made before write-back is enabled, and none of them are questions about the model:
- Which priority level a supervisory write uses, and which levels must always beat it.
- What happens to that level when the writer stops: a timeout that relinquishes to NULL, or station logic that clears it.
- The clamp, meaning the range outside which a recommended value is refused at the station rather than written to the equipment.
- Who is told when a write is refused, clamped or relinquished, and where that appears, since a silently rejected recommendation looks exactly like one that was accepted and did nothing.
Where a Rule Already Does the Job
A large share of what gets sold as machine learning fault detection is a threshold and a timer. Stuck valve, short cycling, simultaneous heating and cooling, a sensor reading outside its physical range, a damper commanded one way while the temperature moves the other: these are deterministic rules over a handful of points, and they beat a learned model on the thing that matters operationally, which is that they name the fault instead of scoring the hour. ASHRAE Guideline 36 goes further and writes a set of these alarms into the sequences of operation themselves, so on a job built to it, part of the fault list is already specified and already executing in the controller rather than waiting on a layer above.
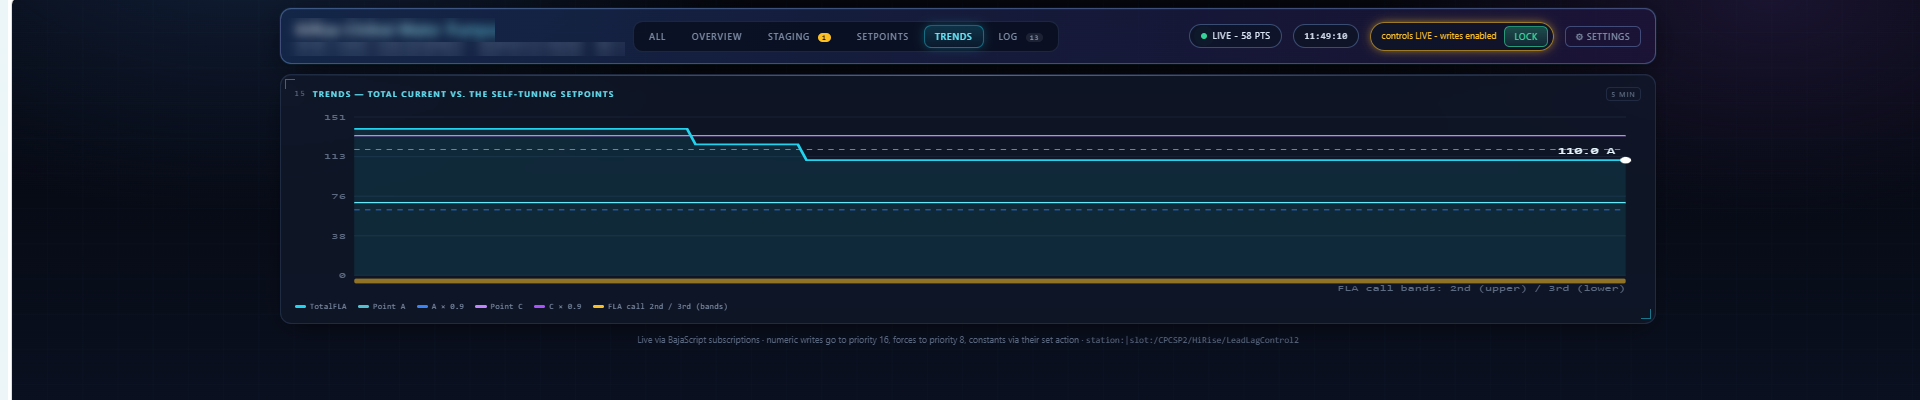
What a rule cannot do unaided is catch slow drift, because drift needs a reference and a lone sensor has none. The available references are physical rather than statistical, and if none of them exists on the equipment in question, the honest answer is instrumentation rather than analytics:
- A mixed air temperature that has to fall between return and outside air, weighted by damper position.
- Two sensors on the same header, or supply and return on a loop where flow is known.
- A main meter against the sum of the submeters beneath it.
- A relationship the equipment cannot physically violate, such as a coil that keeps cooling with its valve commanded closed, which turns any violation into a sensor question rather than a mystery.
When the Honest Answer Is Not Yet
Some buildings are not ready for an intelligent layer, and they are recognizable in advance. If the existing alarm console already produces findings that nobody acts on, a layer producing more findings raises the ignore rate rather than the response rate, because the bottleneck is the response process and not detection. If the points that would answer the question were never installed, no amount of modeling substitutes for a sensor. And if collection only recently started, anything weather dependent has no baseline yet, since comparing a chiller against outside air temperature requires having seen a range of outside air temperatures.
The other thing worth knowing before committing is that the ongoing cost of an intelligent layer is not the model, it is the mapping. Every controller replacement, retrofit, renamed point and added piece of equipment breaks part of the correspondence between the building and its representation, and it breaks quietly: the analysis keeps running against the stale version and keeps looking plausible. Someone has to own that maintenance. When the model lives in the station, in tags and relations rather than in an external spreadsheet, the maintenance at least happens in the same place as the change that caused it.
Frequently Asked Questions
Does an AI layer take control of the building?
There is a test that settles it: disconnect the analytics layer and watch what changes. Sequences, schedules, interlocks and alarms execute in the JACE and in the field controllers beneath it, which is why a correctly built system keeps running unchanged when a supervisory or cloud service goes away. If disconnecting the layer changes what the equipment does, that layer is in the control path regardless of what the sales material called it. Where a supervisory write genuinely is wanted, it belongs at a defined priority level with a relinquish path, which is a different arrangement from control.
What has to already exist before any of this is worth doing?
Four things: points that resolve to identifiable equipment, units on those points, history collection at an interval that can actually show the behavior in question, and someone who will act on what comes out. The first three are fixable and usually account for the bulk of the work. The fourth is not something an integrator can supply, and a building can be thoroughly instrumented and still not ready if nothing in the process turns a finding into a work order.
How does an analytics layer connect to a Niagara station?
Over the station's web service rather than over Fox. Workbench and Supervisor-to-JACE traffic uses Fox on 1911, or FOXS on 4911 with TLS, and that is an engineering channel rather than an integration API. For read access, a Niagara 4 station serves HTTPS on 443 by default and can expose data through oBIX with the obixDriver module, through a Haystack REST endpoint where the nhaystack module is installed, or by archiving histories into an external database the analytics layer queries directly. Whichever path is used, it should run as a dedicated read-only user with its own credentials, so access can be audited and revoked without disturbing anyone else.
How does the work actually proceed, in what order?
Inventory first: list the points that exist against the points the intended questions require, because the gap between those two lists governs everything after it. Then correct the station side, which means naming, tags and relations, units in facets, and history extensions set to the right type, interval and capacity. Then expose read access and let the histories accumulate the depth the specific analysis needs. The analytics or question-answering layer is built last, and it depends on all of the preceding steps rather than the reverse.
What does the customer have to provide or decide?
Provide: a network path to the station, credentials for a read-only user, and documentation for anything that is not self-describing, which in practice means vendor register maps for Modbus devices and points lists or submittals for equipment that was integrated rather than natively controlled. Decide: which equipment matters enough to model properly, who owns the naming and tagging convention where existing names conflict, whether any write-back is permitted and at what priority, and who receives findings and is expected to act on them. Of those, the tagging convention is the decision that most directly shapes how the finished system answers questions.
What if the site is not running Niagara?
Then the first question is where the point descriptions live, and on a Modbus site the answer is the vendor's register map document. The protocol carries 16-bit registers and nothing else: a 32-bit value spans two of them and the word order across the pair is a vendor choice you have to be told or determine empirically, and a single read of holding registers returns at most 125 of them, so a large map becomes many round trips. BACnet devices describe themselves considerably better, as covered above, but no protocol read supplies equipment relations and, in Modbus's case, there is no self-description at all. The modeling still has to happen; with no station to hold it, it happens inside the analytics layer, once per site, and is maintained there.
Can it answer plain-language questions about the building reliably?
It can, to the degree that a question resolves to specific points rather than to text resembling them. Retrieval over a tagged model can find the discharge air temperature on a named air handler because the tags and relations say what it is; retrieval over untagged point names finds whatever string looks closest, and a language model presents that with the same confidence as a correct match. Two things make the answers checkable: citing the point path and record timestamp alongside the answer, and taking units from the station's facets rather than inferring them from a name. Read-only access also bounds the damage of a wrong match to a wrong answer instead of a wrong command.
Recorded Demonstrations
The recordings below show this work running rather than described. They open on YouTube in a new tab.
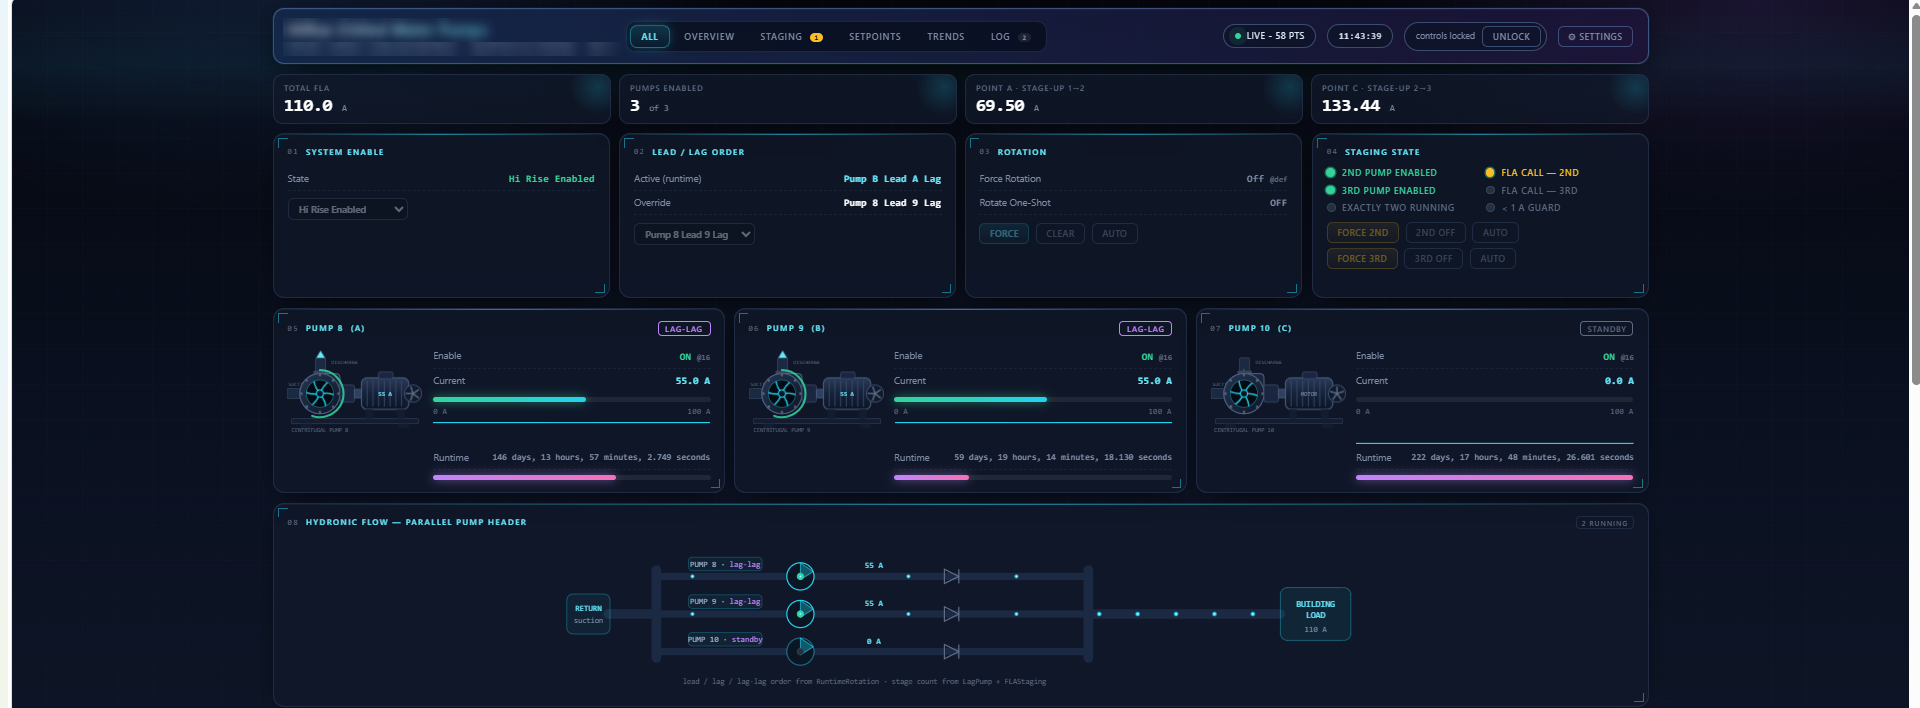
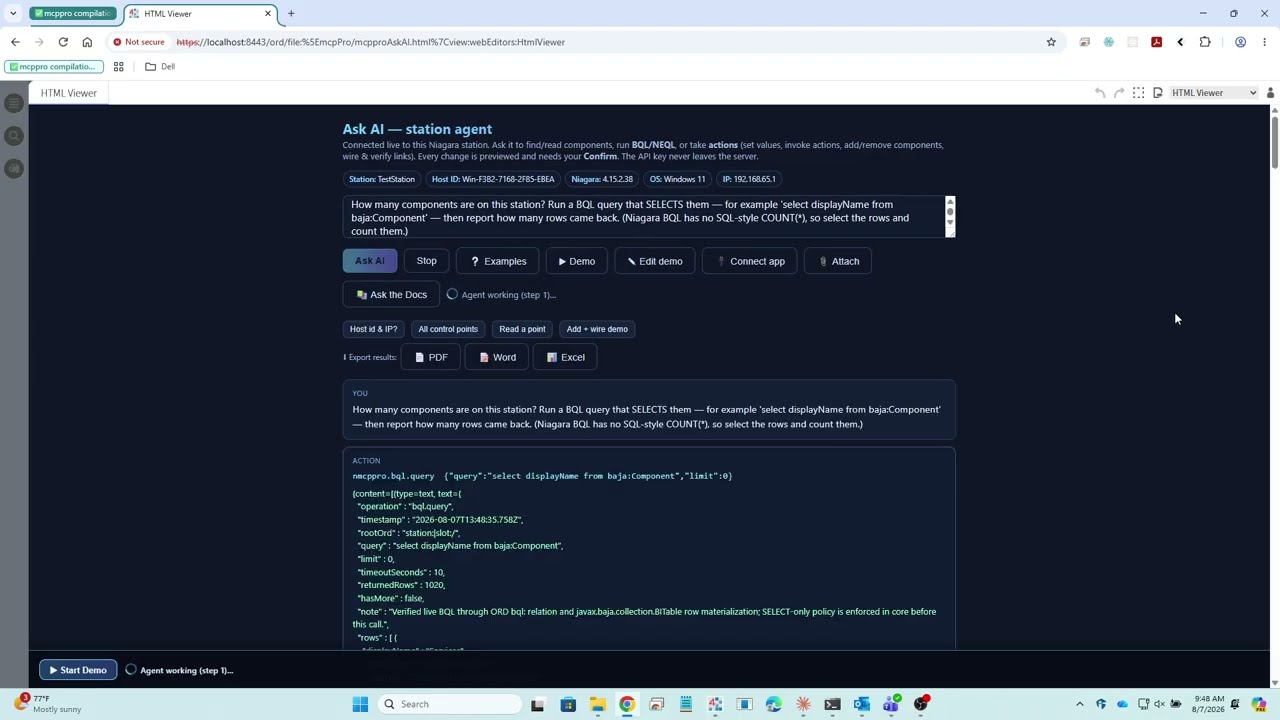 56:57Niagara N4 AI bot: operating a building-automation station in plain English80 recorded demonstrations across operations, engineering, integration and supervision.
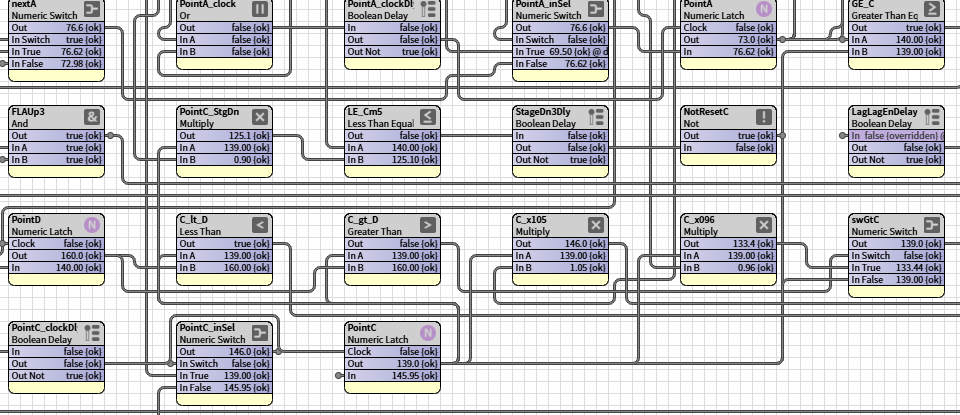
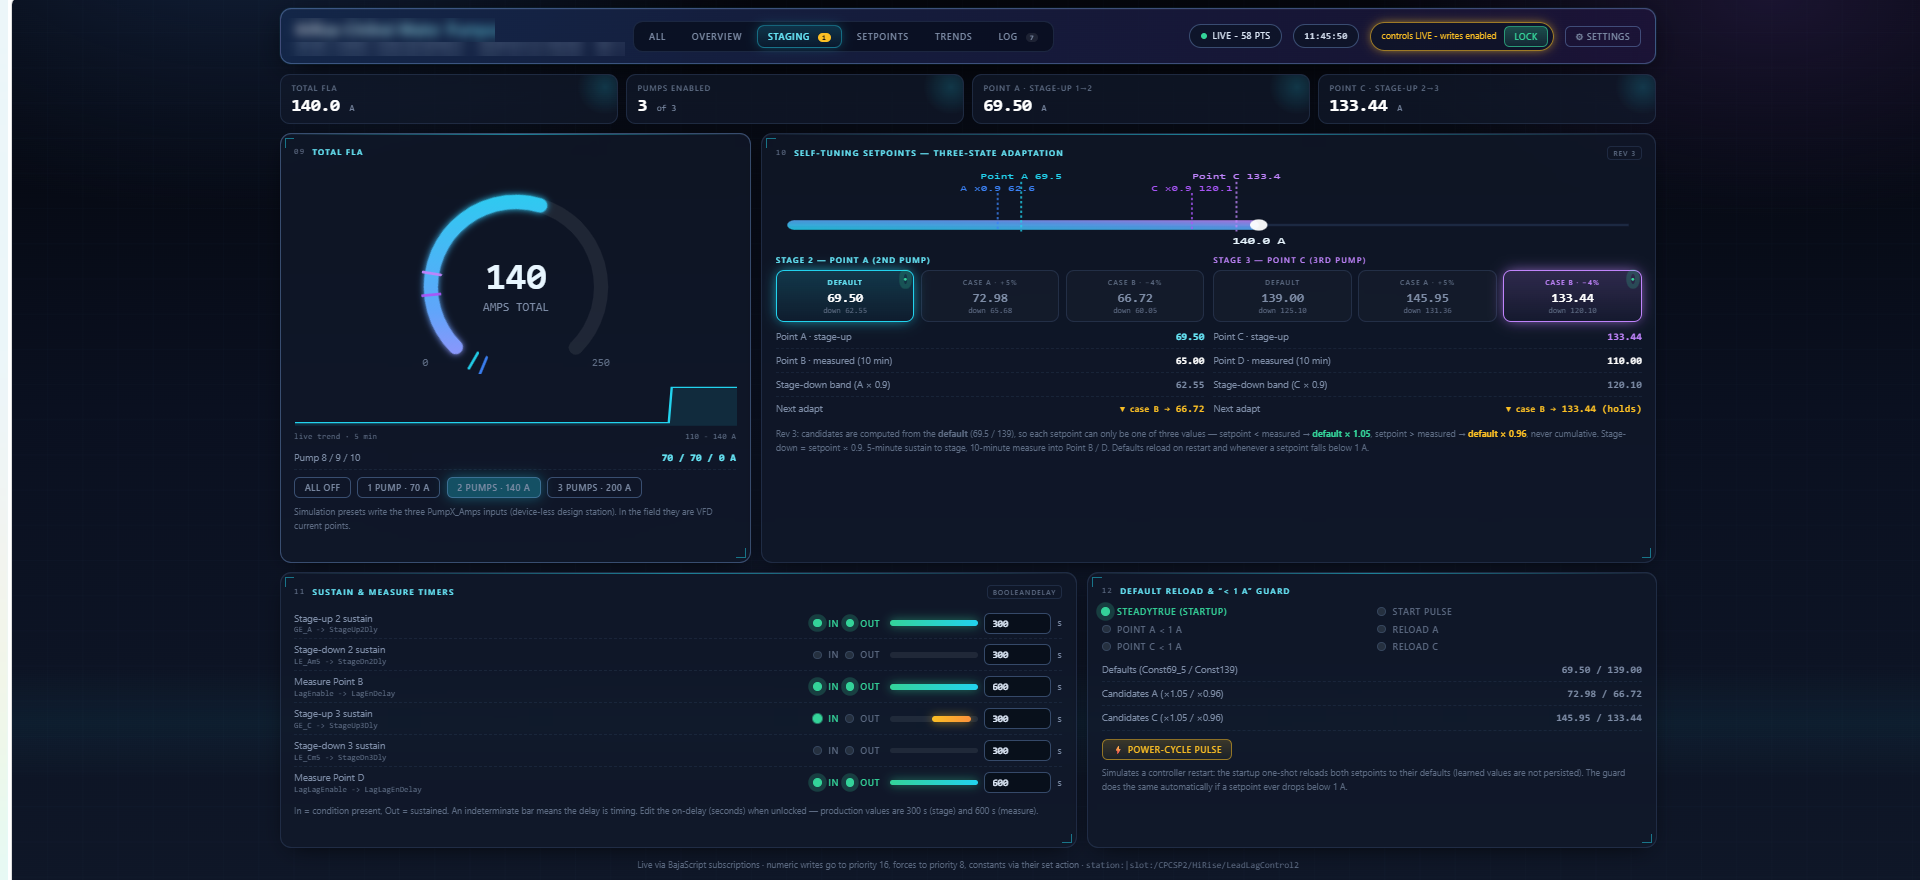
 2:17AI-generated Supervisor wiresheets and dashboardsWiresheet logic and dashboard views produced by the bot in a Niagara Supervisor.
 4:31AI-generated Supervisor wiresheets and dashboards, second exampleA further worked example from the same series.
Inside the Niagara MCP Module
The module behind the recordings above is an in-station Model Context Protocol server. It gives an agent discovery-driven control of a live Niagara station: enumerate the installed modules, list the instantiable types, reflect a type slots on a transient unmounted instance, then create components, set slots, invoke actions and link wiresheet slots. Because Niagara is a uniform component model, that generic layer reaches any module rather than needing an adapter written per driver family.
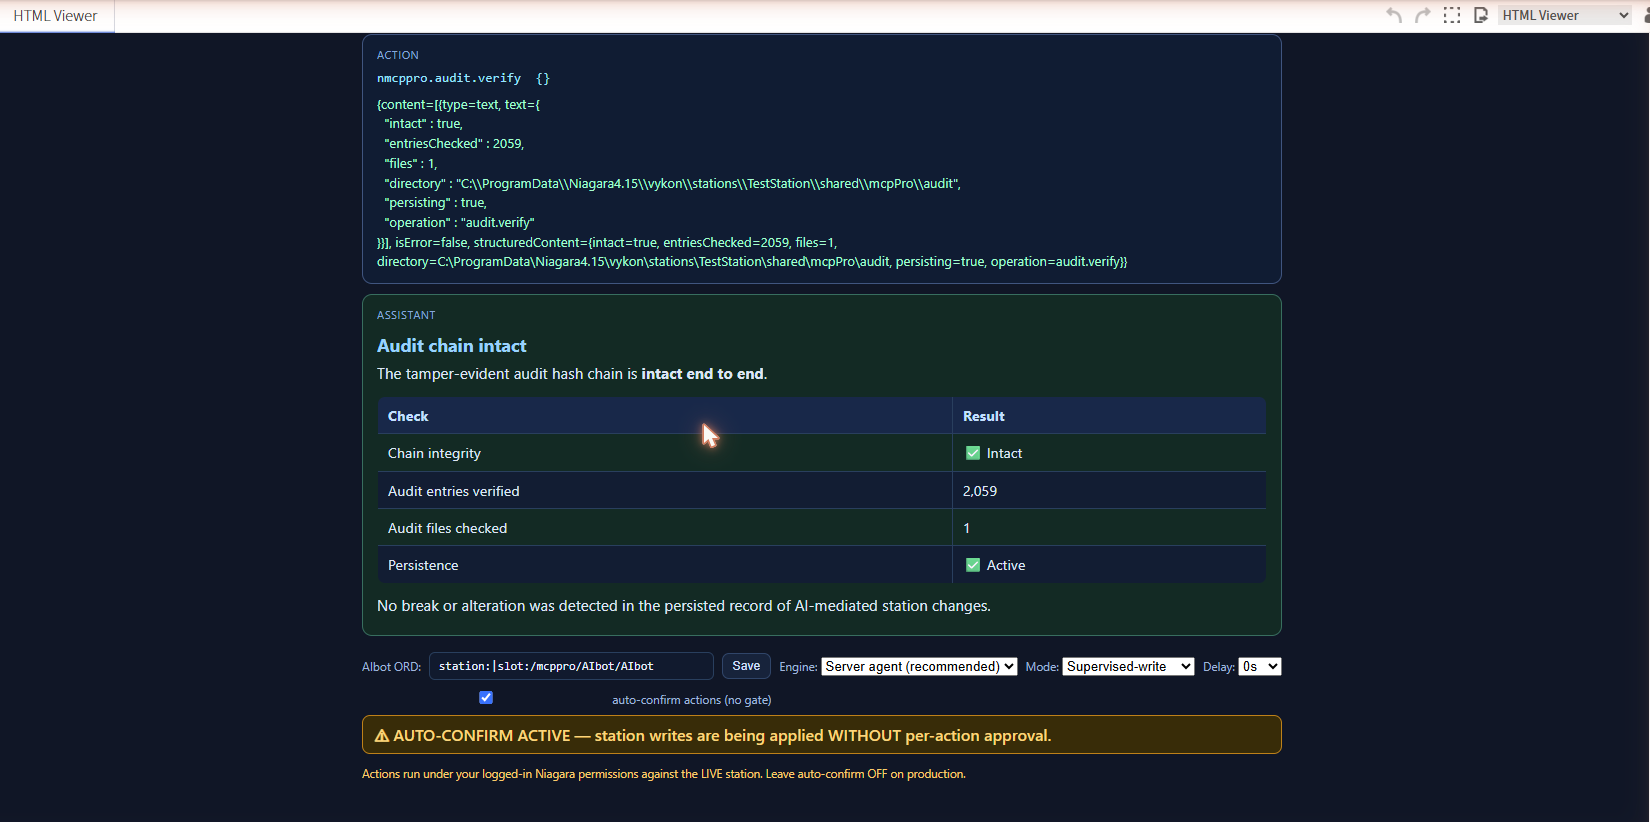
Every write sits behind an explicit gate, runs bound to a real Niagara user, and is audited. Five capability gates covering BACnet discovery, security writes, module installation, station administration and performance telemetry all default to off and fail closed: calling a gated tool with its gate off names the exact property and runs nothing.