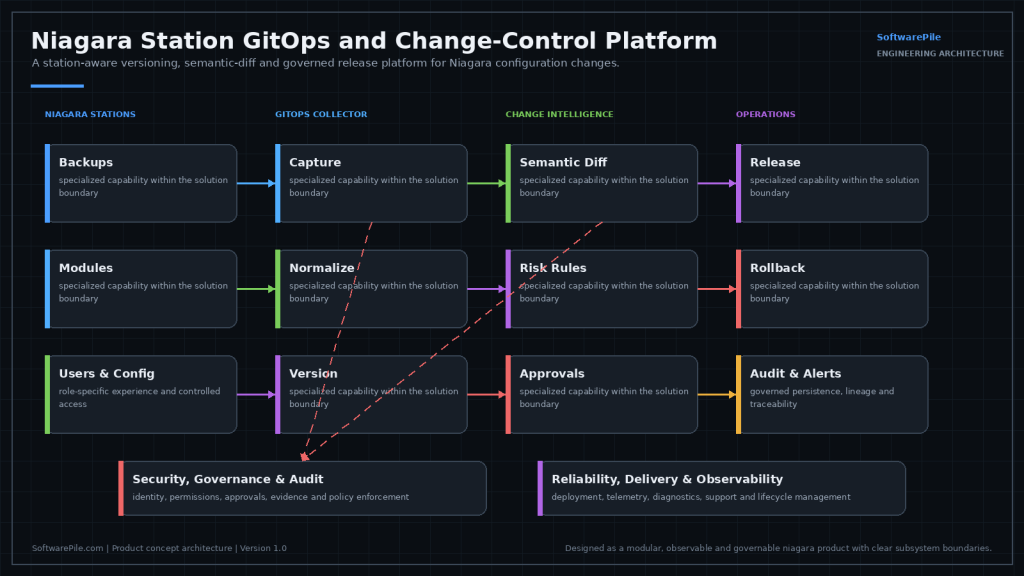
Station backups tell you that something changed. They almost never tell you what. A file is different, a date moved — but did someone adjust a setpoint, rewire control logic, disable an alarm, or add a user? On systems that run buildings, that distinction matters, and today it is usually reconstructed from memory.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
Designed Capabilities
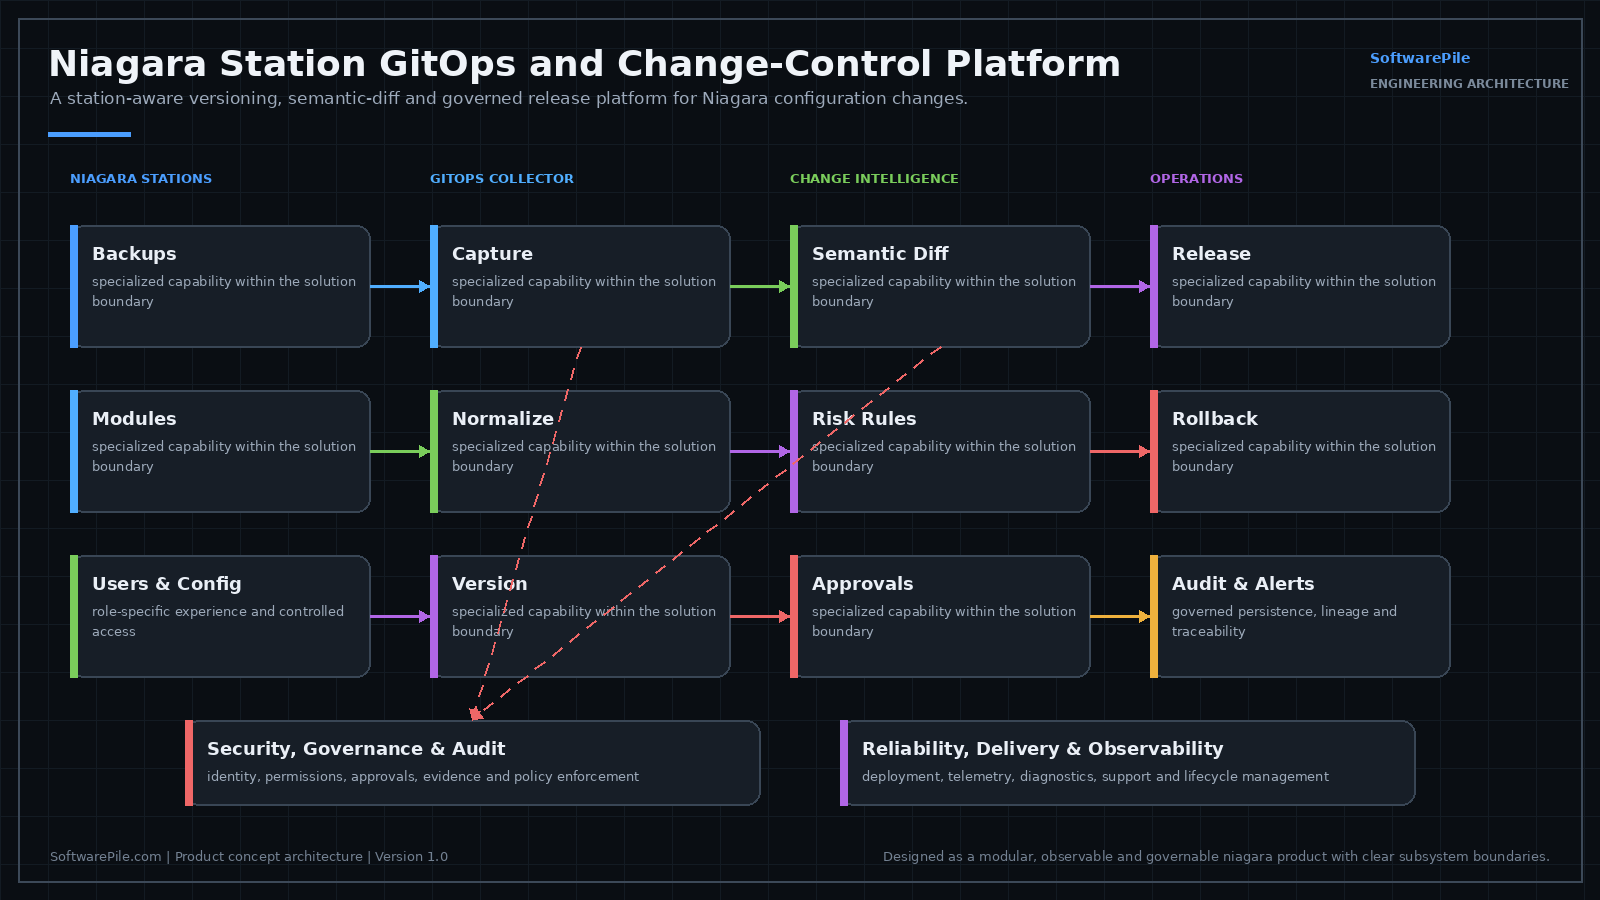
- Scheduled station backup capture — the baseline, taken reliably rather than when someone remembers.
- Normalized station representation — a form that can actually be compared.
- Semantic component and link diff — what changed in the logic, not which bytes moved.
- User, module and permission change detection — security-relevant changes called out separately.
- Approval and release workflow — changes to production get reviewed, like any other system.
- Release notes and evidence package — a record for the client and the auditor.
- Rollback bundle generation — a way back that was prepared, not improvised.
- Unauthorized-change alerts and retention policies — know when something changed that shouldn’t have.
Building Automation Deserves Software Discipline
Every other part of the software industry settled this decades ago: changes are versioned, reviewed, released and reversible. Station configuration — which controls physical plant — is often still managed by copying files to a folder. Bringing ordinary engineering discipline to it is overdue, and the semantic diff is what makes it practical rather than theatrical.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
Related services
- Custom Niagara Module and Driver Development — Change control for station code sits alongside custom module and driver development.
What a Semantic Diff Has to Ignore
A comparison is only useful if it stays quiet when nothing meaningful happened. Two captures of an untouched station are rarely identical: timestamps move, cached values get written back, connection and subscription state is persisted, and serialization order is not guaranteed to be stable between saves. A comparison that reports all of that produces a full page of changes every night, and a report nobody reads is the same as no report.
Most of the engineering effort therefore goes into deciding what does not count, not into the comparison itself. Components have to be matched by identity and path rather than by position in a file, so that a block moved under a different folder reads as a move instead of a deletion plus an unrelated addition. Configuration has to be separated from runtime state, because a station doing its job changes state constantly and changes configuration rarely. Getting that boundary wrong in either direction is the main way this kind of tooling fails: too loose and it is noise, too aggressive and it hides the edit you needed to see.
- Volatile runtime state: present values, alarm and subscription status, connection status, poll and sync stamps. Not treated as a change.
- Ordering and serialization differences that carry no meaning. Normalized away before anything is compared.
- Component identity: matched by path and handle so that renames and moves are described as renames and moves.
- Credential-bearing and encrypted fields: reported as having changed without reproducing their contents anywhere in the output.
Start With the Baseline, Add Review When There Is Someone to Approve
The platform is built in layers and a site does not have to adopt all of them at once. Where there is no dependable history of a station today, the useful starting scope is the capture and retention layer on its own: a baseline taken on a schedule and kept long enough that comparisons have something real to run against. The review and release workflow sits on top of that layer and is worth switching on once there is a named person who can accept a change and a working definition of what production means at that site.
There are also situations where the review layer will not earn its keep, and saying so is more useful than selling it. A single engineer holding the only platform credentials, working on a station nobody else touches, already knows what changed; what is missing there is the record, not an approval step. A station still being built out before handover changes constantly by design, and gating those edits only slows the work down. Stations owned and maintained by a manufacturer or another contractor, where platform access is not available to you, are outside the reach of any of this, and no tooling changes that.
What the Platform Needs From a Site
Most of the dependencies here are about access, and access is usually the slowest part of getting started. Covering a station means a network path to each JACE and Supervisor in scope, credentials that can read station configuration and take a backup, and an agreement about where that path comes from: a jump host, a VPN, an existing remote support route, or a collector running on the site network.
The fleet itself sets the rest of the limits. Controllers differ in what they can spare while a capture runs, and sites on metered or thin links care how often a full capture crosses the connection, so capture frequency belongs to each site rather than to a single global setting. Mixed Niagara versions across a fleet are normal and the normalized representation exists partly to absorb that, but an older release can expose less structure than a current one, and a diff can only report what the station is able to describe about itself.
- Network reachability to every station in scope, and a decision about how that path is provided.
- Read credentials for station configuration and backup, preferably a dedicated account rather than a shared engineering login.
- Storage the customer controls for the captured history, sized for the retention period the customer needs.
- An inventory of what is in scope and what is deliberately excluded: test benches, stations under construction, third-party maintained equipment.
- A named owner for the review step, once the review layer is in use.
Rollback Is Not the Same as Restoring a File
Putting a station back is harder than it sounds, which is why a rollback bundle is generated rather than assumed to exist. A station is not self-contained: it carries device addressing, driver and network configuration, license and certificate material, and history that has kept accumulating since the capture was taken. Restoring one wholesale can undo a bad logic edit and, in the same motion, revert an unrelated point that somebody legitimately added the same week.
The design intent is to make the scope of a revert explicit before anyone runs it. If the change under review touched a control block and its links, the bundle should say what returning that block involves, what else has moved since, and what an engineer has to confirm first. It should be equally clear about what software cannot undo: if a device was physically removed or a field wire was moved, no configuration rollback puts that back, and the honest job of the record is to say so rather than to imply a clean reversal.
Frequently Asked Questions
What is this platform, and what is it not?
It is a change-control layer that sits beside a Niagara installation rather than inside the engineering work that produces changes. It is not a replacement for Workbench, it is not a Supervisor, and it is not operational monitoring: it does not manage alarms, trends or graphics, and it will not tell you whether a building is running well. It reads station configuration rather than writing to stations, and a rollback bundle is prepared for an engineer to apply rather than pushed automatically. It is still in development, so everything described here is design intent, not something that can be bought or deployed today.
Does using it require our team to adopt Git?
No. Engineers keep working in Workbench as they do now, and nobody is asked to learn commit syntax or a branching strategy. The version history can live in a repository your organization already runs or in storage you control, which is a deployment choice rather than a change to how stations are engineered. What a reviewer reads is station components, links and properties, described in Niagara terms.
What does it run on, and what has to already exist?
It is designed to run as a service alongside the stations it covers, on customer infrastructure or in a hosted deployment, with a collector that can reach each JACE and Supervisor in scope. What has to exist already is the Niagara installation itself, a network path to those stations, and credentials able to read configuration and take a backup. The baseline capture and comparison are designed not to require anything installed into production stations; if some capability ever does need to run on a station, that is treated as an exception to be called out rather than a default. None of this is deployable yet, so these are the constraints being built to.
We already have a Supervisor taking backups. Does this replace that?
No, and it works either way by design: it can take captures on its own schedule, or read backups that an existing Supervisor or backup job already produces. The value being built sits in the normalization, comparison and record kept on top of those captures, not in the act of collecting them. Where a backup routine already runs dependably, the sensible choice is to leave it alone and read from it. Where captures are irregular, or nobody can say when the last one ran, the platform takes the schedule over.
How would a rollout actually proceed?
In order: agree which stations are in scope, establish access and a dedicated read account, capture a baseline, then let it run for a while with nobody acting on the output. That quiet period is what lets the noise filter be tuned to your particular fleet, since every fleet has its own harmless churn. Change alerts then go to a small audience first, so the filter can be corrected before a wide audience learns to ignore it, and the approval and release workflow comes last, once there is history worth reviewing against and a named approver. A restore should be exercised on a test or non-production station before anyone depends on it.
How is it meant to integrate with the systems we already run?
The integrations that matter sit at either end of a change: where the history is kept and where people are told. History is designed to go into a repository or storage you control, in a form you can export rather than one that only this platform can read. Notification is designed to reach whatever a team already watches, so that a change is raised where the team is instead of in a console someone has to remember to open. Sign-in is intended to use your existing directory or single sign-on, so reviewers and approvers are the same identities you manage elsewhere.
What do we have to provide or decide?
Access, scope, and an approver. Access means the network paths and credentials described above; scope means which stations are covered and which are deliberately left out; the approver decision means naming who can accept a change to a production station and what counts as production at that site. You also decide where history is stored and how long it is kept, since retention is normally driven by your own audit or contractual obligations rather than by us. Without an answer to the approval question, the approval workflow has nothing to enforce, and the capture and comparison layers are the parts still carrying their weight.
Who can see the data, and what stays under our control?
Station configuration is your data and the design keeps it that way: history lives in storage you control or in a deployment you own, and the record of what changed is yours to export and retain. Roles are meant to be separated, so that reading a comparison, approving a release and administering the platform are not the same permission. Credential-bearing and encrypted fields are reported as changed without reproducing their contents in a comparison or an evidence package. In a hosted deployment, what we can see is a decision made at deployment time, and support access is intended to be granted explicitly rather than left standing.